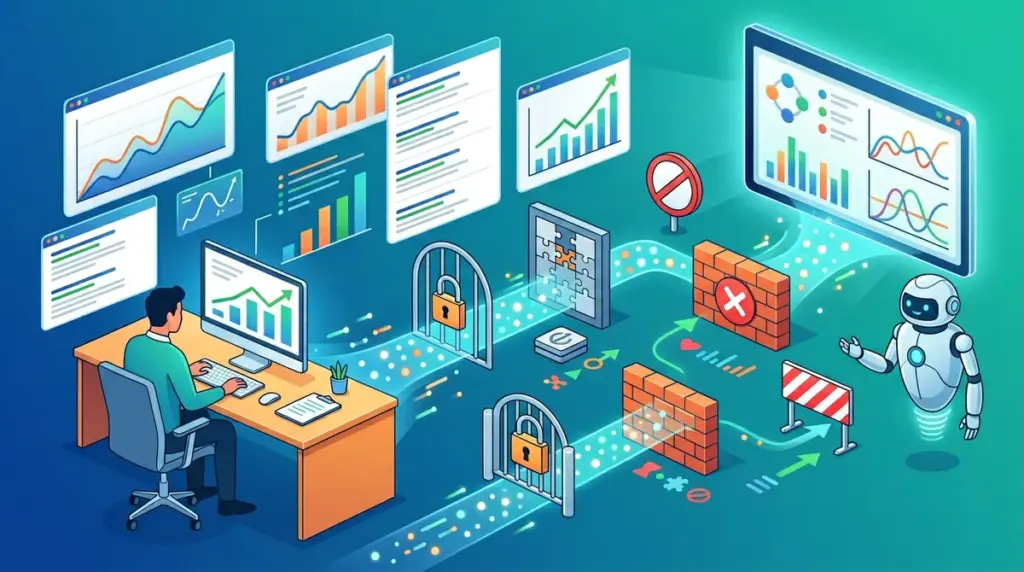
Checking search engine rankings at scale is a constant battle against automated detection systems. If you have ever been met with a "429 Too Many Requests" error or a persistent CAPTCHA wall, you are experiencing Google’s perimeter defense. For SEO agencies and publishers, these blocks do more than slow down reporting; they lead to incomplete data sets and skewed performance metrics. To maintain a reliable flow of keyword data, you must move beyond basic scraping and adopt an infrastructure that mimics legitimate user behavior while managing technical identifiers.
The Mechanics of Search Engine Rate Limiting
Search engines do not block bots simply because they are bots; they block them because they consume massive resources and can be used for malicious scraping. Detection typically triggers based on three primary signals: IP reputation, request velocity, and browser fingerprinting. When you send 500 queries from a single static IP within a minute, you deviate from any possible human pattern. The search engine responds by flagging the IP and serving a CAPTCHA to verify the "humanity" of the request. If the behavior persists, the IP is temporarily or permanently blacklisted.
IP Reputation and Proxy Categorization
Not all IP addresses are treated equally. Google maintains databases of IP ranges associated with major data centers like AWS, Azure, and DigitalOcean. If your rank-checking script runs from a server in one of these ranges, the threshold for triggering a block is significantly lower. Residential IPs, which are assigned by Internet Service Providers (ISPs) to home users, carry the highest trust. Mobile IPs (4G/5G) are even more resilient because multiple users often share a single mobile IP, making search engines hesitant to block them and risk impacting legitimate customers.
Browser Fingerprinting Beyond the User-Agent
Modern detection goes far beyond checking your User-Agent string. Search engines use JavaScript to probe for "headless" browser characteristics. They look for the presence of the navigator.webdriver property, specific screen resolutions, available fonts, and hardware concurrency. If your scraper claims to be a Chrome browser on Windows but lacks the expected WebGL signatures or Canvas rendering patterns, it will be flagged as a bot regardless of how clean your IP is.
Strategic Proxy Deployment
To check rankings without interruption, you must decouple your scraping logic from your local IP. This requires a sophisticated proxy strategy. Best for high-volume agencies: A rotating residential proxy network that automatically switches IPs for every request or every session.
- Datacenter Proxies: Fast and inexpensive, but easily detected. Use these only for low-frequency checks on less restrictive search engines.
- Residential Proxies: These provide the best balance of cost and reliability. They are essential for localized SERP tracking (e.g., checking rankings in a specific zip code).
- Mobile Proxies: The most expensive option, but virtually unblockable. Use these as a fallback for highly competitive keywords where Google’s bot detection is most aggressive.
Warning: Avoid using "free" proxy lists found online. These are almost always compromised, monitored, or already blacklisted by every major search engine. Using them can leak your proprietary keyword lists to third parties and will result in a 100% failure rate for SERP data collection.
Mimicking Human Interaction Patterns
Even with a clean proxy, a robotic request pattern will eventually trigger a block. Search engines analyze the "jitter" or variance between requests. If a request arrives exactly every 5.00 seconds, it is clearly automated. To bypass this, you must implement request throttling and randomization.
Instead of a fixed delay, use a randomized interval. For example, if you need to average one request every ten seconds, set your script to wait between 7 and 15 seconds. Furthermore, vary the time of day you perform your checks. Running 10,000 keyword checks at exactly 2:00 AM every Tuesday creates a footprint. Distributing those checks across a wider window or varying the start time makes the activity less conspicuous.
Advanced Header and Fingerprint Management
To remain undetected, your automated browser must be indistinguishable from a standard consumer setup. This involves more than just rotating User-Agents. You must manage the entire header stack, including Accept-Language, Referer, and Sec-Fetch headers. If you are checking rankings in France, your headers should reflect a French-speaking user, likely using a localized version of a browser.
Pro Tip: Use headless browser management libraries like Puppeteer-Extra with the Stealth plugin. These tools automatically patch the common leaks that reveal a browser is being controlled by software, such as the chrome.runtime property or specific CSS quirks found only in automated environments.
The Case for Managed SERP APIs
For many businesses, the overhead of managing proxies, solving CAPTCHAs, and updating scraping logic every time Google changes its HTML structure is not cost-effective. This is where managed SERP APIs become commercially viable. These services handle the entire infrastructure layer—proxy rotation, browser fingerprinting, and CAPTCHA solving—and return a structured JSON response.
Best for: Developers and data scientists who need raw SERP data without the headache of infrastructure maintenance. By offloading the "cat and mouse" game of bot detection to a specialized provider, you can focus on data analysis rather than troubleshooting 403 errors.
Auditing Your Rank Tracking Infrastructure
If you are currently experiencing blocks, perform a systematic audit of your setup. Start by checking your success rate per proxy provider. If your datacenter proxies have a failure rate higher than 15%, it is time to shift to a residential pool. Next, examine your request headers. Ensure they are not "naked"—standard browsers send a variety of headers that many basic scripts omit.
Finally, monitor your CAPTCHA trigger rate. If you see an uptick, it is a signal that your browser fingerprint is being identified. Simply changing the IP won't help if the fingerprint remains the same. You must rotate your browser profiles or update your stealth configurations to match the latest version of mainstream browsers.
Frequently Asked Questions
Does using a VPN prevent CAPTCHAs when checking rankings?
Generally, no. Most commercial VPN IPs are heavily used and are often flagged by search engines. While a VPN hides your personal IP, it usually places you on a "dirty" IP that is more likely to trigger CAPTCHAs than a standard home connection.
How many keyword checks can I safely do from one IP?
There is no hard limit, but a safe rule of thumb for a standard residential IP is 10 to 20 queries per hour with randomized delays. Anything higher risks a temporary block or a CAPTCHA challenge.
Will using a headless browser make my rank checking slower?
Yes, because a headless browser must render the page, execute JavaScript, and load assets, it is significantly slower than a simple GET request. However, it is much more effective at avoiding blocks and allows you to capture data from dynamic SERP features like Map Packs and People Also Ask boxes.
Is it legal to scrape search engine rankings?
In many jurisdictions, scraping publicly available data is legal, but it often violates the search engine's Terms of Service. This is why search engines use technical blocks rather than legal action to prevent large-scale scraping.